#PYDATA
Beautiful Leaflet Markers with Folium and Font Awesome
TIL how to use fontawesome markers with folium. Read more →
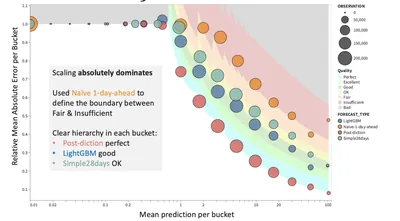
Scale-Aware Rating of Count Forecasts
Forecasts crave a rating that reflects the forecast's quality in the context of what is possible in theory and what is reasonable to expect in practice. Read more →
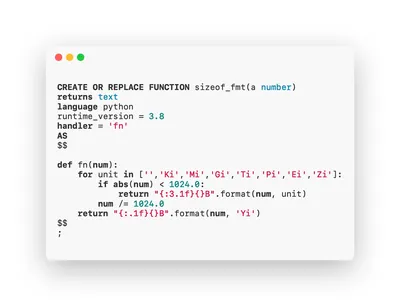
Python Support in Snowflake
Snowflake offers different ways to access and call python from within their compute infrastructure. This post will show how to access python in user defined functions, via stored procedures and in snowpark. Read more →
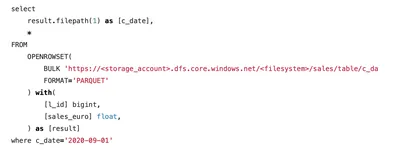
Azure Synapse SQL On-Demand OPENROWSET Common Table Expression with SQLAlchemy
Using SQLAlchemy to create openrowset common table expressions for Azure Synapse SQL-on-Demand Read more →
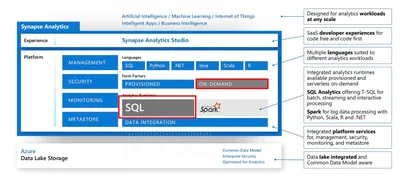
DuckDB vs. Azure Synapse SQL on-demand with Parquet
Inspired by Uwe Korns post on DuckDB this post shows how to use Azure Synapse SQL-on-Demand to query parquet files with T-SQL on a serverless cloud infrastructure. Read more →
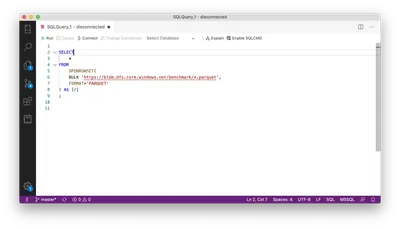
Using turbodbc to access Azure Synapse SQL-on-demand endpoints
Azure Synapse SQL-on-Demand offers a web client, the desktop version Azure Data studio and odbc access with turbodbc to query parquet files in the Azure Data Lake. Read more →
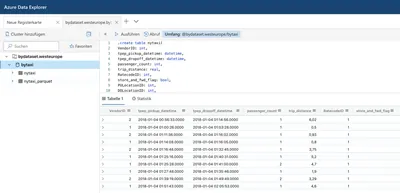
Azure Data Explorer and Parquet Files in Azure Blob Storage
Last summer Microsoft has rebranded the Azure Kusto Query engine as Azure Data Explorer. While it does not support fully elastic scaling, it at least allows to scale up and out a cluster via an API or the Azure portal to adapt to different workloads. It also offers parquet support out of the box which made me spend some time to look into it. Read more →
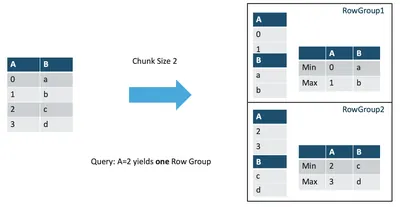
Understanding Predicate Pushdown at the Row-Group Level in Parquet with PyArrow and Python
How predicate pushdown works on row group level in Apache Parquet, and how to use the row group statistics with pyarrow to read only the data you need. Read more →
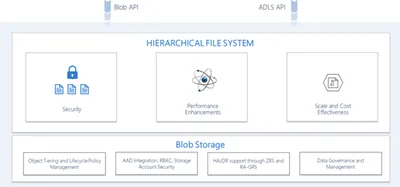
Azure Data Lake Storage Gen2 with Python
Microsoft has released a beta version of the python client azure-storage-file-datalake for the Azure Data Lake Storage Gen 2 service with support for hierarchical namespaces. Read more →
Exasol User Group Karlsruhe
Exasol on Microsoft Azure – automatic deployment in less than 30 minutes Read more →
Getting Started with the Cloudera Kudu Storage Engine in Python
Cloudera Kudu is a distributed storage engine for fast data analytics. The python api is in alpha stage but already usable. Read more →
EuroPython 2015 PySpark - Data Processing in Python on top of Apache Spark
Recording of my EuroPython 2015 talk on PySpark: data processing in Python on top of Apache Spark with RDDs and the DataFrame API. Read more →
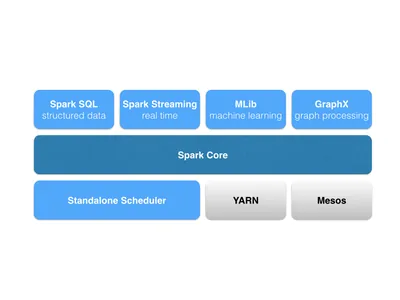
PyData 2015 Berlin - Introduction to the PySpark DataFrame API
My talk at PyData 2015 Berlin with an overview of the PySpark DataFrame API. Read more →